Frequently Asked Questions
1. Access & Onboarding
When I try to log in, I get “Connection closed by 171.67.99.202 port 22”.
This usually means your account is not yet fully activated. Make sure you received a confirmation mail and if the problem persists beyond that, please post to the #marlowe-researchers Slack channel or optionally email srcc-support@stanford.edu.
What’s the estimated timeline for application approval?
Approval time varies. If you have an urgent request, please follow up with marlowe-info@stanford.edu.
Can I avoid repeatedly re-entering my password/Duo authentication?
Yes. OpenSSH’s ControlMaster multiplexing reuses one authenticated connection for every session, file transfer and mount that follows it. See reusing a connection for the ~/.ssh/config settings.
Duo succeeds but my SSH session closes immediately. What’s wrong?
The most common cause is that your account isn’t yet in the marlowe-users UNIX group. Please email srcc-support@stanford.edu with your SUNet ID to be added.
Who do I contact for account or quota problems?
- Technical issues (Slurm errors, storage quota): post in
#marlowe-researcherson Slack or email srcc-support@stanford.edu with error messages and job IDs. - Policy or project allocation questions: email marlowe-info@stanford.edu.
- Security incidents: DM Taymoor Arif or Arhat Kobawala immediately.
How do I grant access to new lab members?
PIs cannot currently manage their Marlowe workgroup directly. The PI should email marlowe-info@stanford.edu with the SUNet(s) to add. Direct workgroup editing may be offered later.
2. Allocations & Accounting
How is usage accounted for on Marlowe?
Marlowe measures usage in GPU-hours (what you may think of as “credits”), tracked per project. When your project is approved you get a project ID, which maps to a Slurm job account. Every job must be charged to a valid account with -A marlowe-<Project ID>; jobs without one fail with:
ACCOUNT ERROR: Did you remember to set your account?
Additional details for specific project types can be found in the Slurm documentation.
Storage in /projects is billed separately via cost-recovery (recharge) — see the Marlowe recharge page.
How do I check project usage and remaining budget?
Use the Slurm accounting tools to see usage against your allocation, e.g.:
Specific account, shown by users:
sreport cluster AccountUtilizationByUser -T cpu,gres/gpu Account=<project> Start=[mm-dd-yyThh:mm:ss] End=[mm-dd-yyThh:mm:ss OR now] -t hours format=Account%30,Login,Proper,Used
Specific user, shown by accounts:
sreport cluster UserUtilizationByAccount -T cpu,gres/gpu user=<username> Start=[mm-dd-yyThh:mm:ss] End=[mm-dd-yyThh:mm:ss OR now] -t hours format=Account%30,Login,Proper,Used
How do I see which accounts and partitions I’m allowed to use?
List your Slurm associations:
sacctmgr show assoc user=$USER format=Account%30,QOS
QOS=normalsubmits topartition=preemptQOS=mediumsubmits topartition=batchQOS=largesubmits topartition=hero
Can I use multiple PTAs for the same project?
The billing system only supports one PTA per project. For questions regarding their PTAs, the PI should contact srcc-support@stanford.edu.
3. Job Submission & Queue Troubleshooting
My preempt job keeps stopping and restarting. Why?
Any job running in the preempt partition may be preempted when a higher-priority job (from the batch or hero partition) needs the same node. When this happens the preempt job is requeued — it is stopped, put back in the queue, and later restarts from the beginning rather than resuming where it left off. This is why it can look like your job “keeps stopping.”
Tip: because preempt jobs are requeued and restarted at any time, checkpoint your work periodically. Save model/optimizer state (and any progress needed to resume) to /scratch at regular intervals, and have your code reload the latest checkpoint on restart. That way a preemption costs you minutes, not the whole run.
I’ve submitted a job and it is still pending. Can I get some idea when it will start?
First check why it’s pending — the reason is usually more useful than a start estimate:
squeue -j <job_id> -o '%.18i %.9P %.8T %.10M %R' # %R = pending reason
For a rough start estimate, ask for the upper bound based on the requested time of jobs ahead of yours:
squeue -j <job_id> --start
More detail on either via:
scontrol show jobid=<job_id>
Why does sbatch say “Invalid account”, “Invalid account/partition combination” or “Invalid qos specification”?
Your account isn’t authorized for the partition you requested (or you named an account you’re not a member of). List your Slurm associations to see the account/QOS combinations you’re allowed to use — see How do I see which accounts and partitions I’m allowed to use?. Then set --account / --partition to an allowed combination.
Which partition should I choose (batch / hero / preempt)?
batch(≤16 nodes, ≤48 hours) — everyday runs, non-preemptible. For approved Medium/Large projects.hero— capability jobs, non-preemptible, highest priority. For approved Hero Runs.preempt— opportunistic, lowest priority. Jobs may be preempted at any time bybatchorherowork and are requeued. Once requeued, the job restarts from the beginning. Ideal for checkpoint-savvy workflows.
Time and node/GPU limits on preempt are adjusted based on demand and are subject to change. Check current values rather than relying on a remembered one:
sinfo -p preempt -o "%P %l"                              # time limit
sacctmgr show qos normal format=Name,MaxTRESPerAccount   # GPU cap (per project)
How much memory is allocated by default?
If you don’t specify -c or --mem-per-cpu, you get 1 CPU and the partition’s default memory per CPU (DefMemPerCPU). That default is configured per partition and is adjusted over time, so check the partition you’re submitting to rather than relying on a remembered figure:
scontrol show partition <partition> | grep -i mempercpu
Note that MaxMemPerCPU is a ceiling, not the default — asking for more than it allows is what gets your request adjusted or rejected. The cluster-wide MaxMemPerCPU is in scontrol show config, but DefMemPerCPU will not be there, since it is a per-partition setting.
What does node state “plnd” mean?
plnd == planned — the node is already reserved for a future job and is not idle.
My salloc + tmux session vanished after an hour. How do I reconnect?
srun --jobid=<myJobID> --overlap --pty bash   # joins the allocation
tmux attach                         # rejoins the tmux session
Interactive job hangs when I spawn many processes on a login node. Why?
Login nodes are shared — heavy process spawning degrades service for everyone. Debug in an interactive Slurm job on a compute node, or submit batch jobs instead.
4. GPU / Distributed Training
Why didn’t my job get any GPUs allocated?
You must explicitly request GPUs for your job in order to use them. Add --gpus=<N> to your sbatch/srun/salloc. For example, the following starts an interactive login shell with one GPU on the preempt partition:
srun -p preempt --gpus=1 -A marlowe-mXXXXXX --pty bash
Did my job actually get a GPU?
From a login node, attach an interactive shell to your running job, then check the job’s GPUs:
srun --jobid=<myJobID> --overlap --pty bash   # attaches you to the job's node
# now you're inside the job and can run:
echo $CUDA_VISIBLE_DEVICES
echo $SLURM_JOB_GPUS
nvidia-smi
Why does CUDA / PyTorch say no GPU, or “CUDA unknown error”?
Most often this is a software problem: a driver / CUDA toolkit / PyTorch-CUDA version mismatch, or changing CUDA_VISIBLE_DEVICES after the process has started. Verify the GPU is visible (see above) and that your framework’s CUDA build matches the loaded toolkit.
If the software checks out, it may be a hardware fault on the node. Faulty nodes are generally drained automatically, but if you land on a bad one, report it in #marlowe-researchers on Slack so others are aware and we can fix it.
My job crashes with CUDA_ERROR_MPS_CONNECTION_FAILED
This can happen in any job that uses CUDA under the hood (PyTorch, JAX, etc.) if a leftover /tmp/nvidia-mps directory from another job is present on the node. To prevent it, load the MPS helper module inside your job:
module load mps
This defines job-specific /tmp directories by setting:
CUDA_MPS_PIPE_DIRECTORY=/tmp/nvidia-mps-$SLURM_JOB_ID
CUDA_MPS_LOG_DIRECTORY=/tmp/nvidia-log-$SLURM_JOB_ID
The module can be loaded anywhere in the job before your CUDA code runs. A Slurm epilog script removes the job-specific directories once the job ends.
Why is multi-node training (NCCL) failing or hanging?
To surface details on the error, turn on NCCL logging, pin the right interface, and launch with srun:
export NCCL_DEBUG=INFO
export NCCL_SOCKET_IFNAME=ib0    # use the InfiniBand interface
srun python train.py
5. Remote Development
I can’t request GPUs using Code-Server through Open OnDemand
Code-Server instances on Marlowe are restricted to 4 CPU cores, 12GB of memory, and 8 hours of runtime. This is to prevent users from sitting on resources without utilizing them.
How do I SSH to compute nodes?
As long as you have a Slurm job running on the node, you can connect with:
ssh <nodename>
What’s the recommended way to use VSCode on a compute node?
Use Marlowe’s Open OnDemand Code-Server app at https://ood.marlowe.stanford.edu, which launches VS Code on a compute node. Running your own code-server / cursor-server / windsurf-server instances on the login nodes is blocked, so Open OnDemand is the supported path.
Why the login-node instances are blocked: direct connections on the login nodes are a violation of the Stanford Network Usage Policy, as they can bypass Stanford’s 2FA requirement.
AI coding / extensions: most VS Code extensions are available in the Open OnDemand Code-Server app — click the Extensions button and search. For Windsurf, install the “Windsurf Plugin” extension. Cursor does not provide an external VS Code extension, so Cursor cannot be used.
Can I use the VS Code or Cursor “Remote - SSH” extension?
No, the “Remote - SSH” extensions are not supported on Marlowe. To edit your Marlowe files from your laptop, mount a Marlowe filesystem with sshfs — see editing files from your laptop. To run VS Code on Marlowe itself, use the Open OnDemand Code-Server app described above.
How do I run Jupyter on Marlowe?
There are Jupyter and marimo applications on Marlowe’s Open OnDemand at https://ood.marlowe.stanford.edu. Each OnDemand application submits an interactive Slurm job and serves it through the OnDemand web server. Queue times can be long when nodes are busy; for fastest job start times keep jobs as short as possible.
6. Storage & Quotas
I receive a “disk quota exceeded” error when writing files. What does this mean and how do I check my quota and inode usage?
Each filesystem on Marlowe has a per-project space and file-count (inode) quota — a dataset stored as many tiny files can exhaust the inode limit long before you run out of space.
The easiest way to see your usage and limits is the storage-quota helper from the marlowe-scripts module, which reports both space and inode usage for a /scratch or /projects directory in one step:
module load marlowe-scripts
storage-quota /scratch/<project>     # your account, e.g. m000047
storage-quota /projects/<project>    # same for a /projects directory
If the inode line is near its limit, store your data in fewer, larger files (e.g. tar up finished runs). For the raw Lustre/NFS numbers, add -r (e.g. storage-quota -r /scratch/<project>).
Home (/users/<sunet>) is a fixed 32 GB intelliflash volume that the helper doesn’t cover yet — check it with du -sh ~, and keep large datasets and conda environments off home (put them on /scratch or /projects).
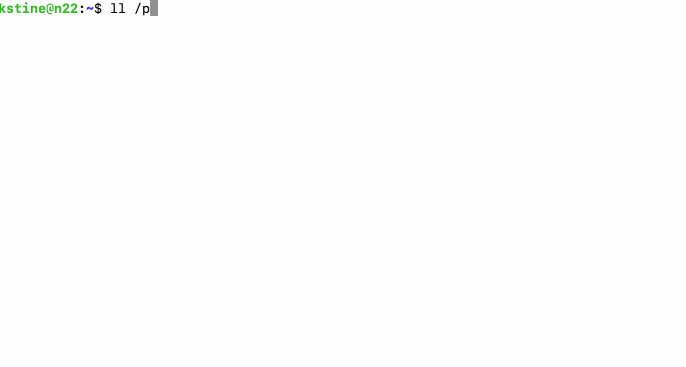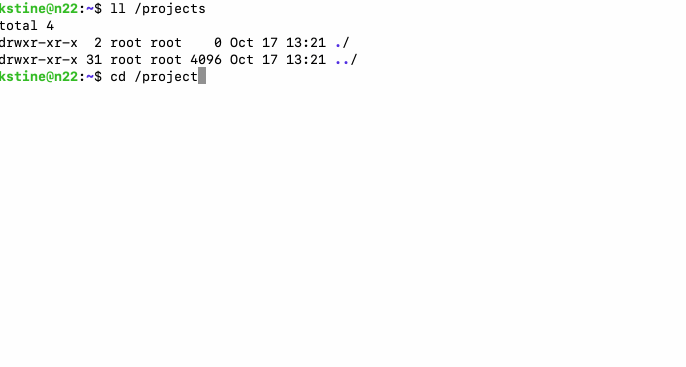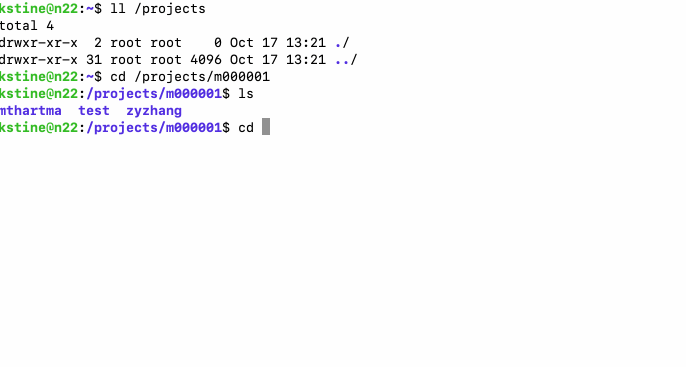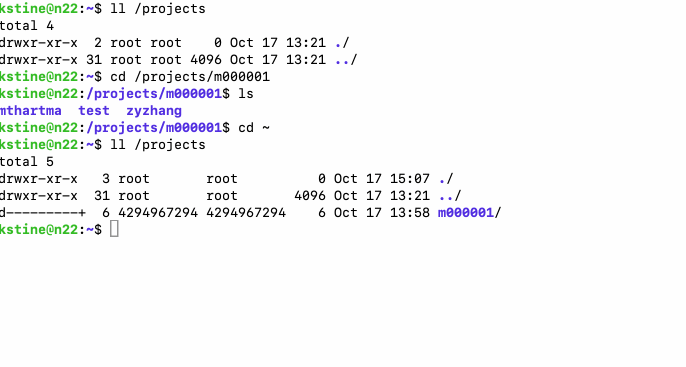
I can’t see my project directory.
The /projects/ filesystem uses autofs to dynamically mount NFS shares. You may not see your /projects/ directory until you first change to the directory after login:
cd /projects/<project ID>
Is /scratch backed up, and can files be deleted automatically?
/scratch is not backed up and may be purged. Any important data should be copied to another filesystem such as /projects on Marlowe, Oak, or cloud storage that is backed up.
Why didn’t my /projects space free up after I deleted files?
Deleted data may persist briefly in backup snapshots, so your quota may not update right away after deleting files. Allow 2–3 hours; if it still hasn’t recovered, ask in #marlowe-researchers.
Note: /projects storage is recharge / cost-recovered — see the Marlowe recharge page.
Which storage should I run my job against?
Run jobs against /scratch (the Lustre parallel filesystem) for best performance, then write final results back to /projects. /scratch is not backed up or snapshotted, so copy anything important to a different filesystem.
For heavy local I/O, use per-job node-local scratch. When your job starts, a directory is created for it automatically at /local_scratch/$USER.$SLURM_JOBID (e.g. /local_scratch/alice.386399) on the compute node. It is only visible from within that job, is not backed up, and is wiped when the job ends — copy anything you want to keep back to /scratch or /projects.
Where do I put large, temporary datasets?
Use your project’s /scratch directory. This is high-throughput Lustre, but it is not backed up and could be subject to purge. Avoid large datasets in home or /projects unless they’re final outputs.
7. Software / Modules / Containers
I can’t run a docker container.
Docker is not supported on Marlowe due to the security risks associated with it. Apptainer supports running docker containers natively:
apptainer pull docker://<image>
apptainer exec <image>.sif <command>
Where are the CUDA tools?
CUDA tools and libraries such as nvcc are in the nvhpc module, which is not loaded by default:
module load nvhpc
I see “A requested component was not found” when submitting an MPI job.
You may see an error like the following when your code doesn’t detect the InfiniBand fabric properly, or gets confused by both Ethernet and InfiniBand:
--------------------------------------------------------------------------
A requested component was not found, or was unable to be opened.  This
means that this component is either not installed or is unable to be
used on your system (e.g., sometimes this means that shared libraries
that the component requires are unable to be found/loaded).  Note that
Open MPI stopped checking at the first component that it did not find.

Host:      n12
Framework: pml
Component: ucx
--------------------------------------------------------------------------
To fix it, reload the fabric libraries in the correct order:
module purge
module load nvhpc
module load gcc/64        # load after NVHPC
The gcc/64 module reloads the network fabric libraries and forces them to be loaded in the correct order. It should be loaded after NVHPC.
The CUDA math libraries appear to be missing in the nvhpc module.
After loading the module, the libraries are present under $NVHPC_ROOT/math_libs. Add that path to LD_LIBRARY_PATH or your CMake search.
8. Data Migration
How do I migrate data off /scratch?
Several options, pick by scale:
- Globus — most performant, best for large transfers.
- rsync / scp — simple, good for small/medium transfers.
- rclone — good for cloud targets; a bit of setup, but well-suited to large-scale movement.
module load rclone
rclone config      # one-time setup
rclone copy /scratch/<path> remote:<dest>